Agent sandboxing: some actions a rollback can't fix
Not every AI agent action can be undone. Classify by reversibility and hard-block the permanent ones before an incident shows you the gap.
8 min read
I run eight production systems, and AI agents write a fair share of the code. They're quick, eager and sometimes confident about things they haven't checked. Here's how I keep them honest: one mechanism a post, drawn on a single notebook page, twice a week.
$ commit "quick fix, trust me"
refused: this change has no approved plan.
Write down what you're changing and why ... then try again.Not every AI agent action can be undone. Classify by reversibility and hard-block the permanent ones before an incident shows you the gap.
8 min read
An AI agent can disable its own monitoring if the checks live in its process: here is how an external supervisor with two hard timeouts actually works.
11 min read
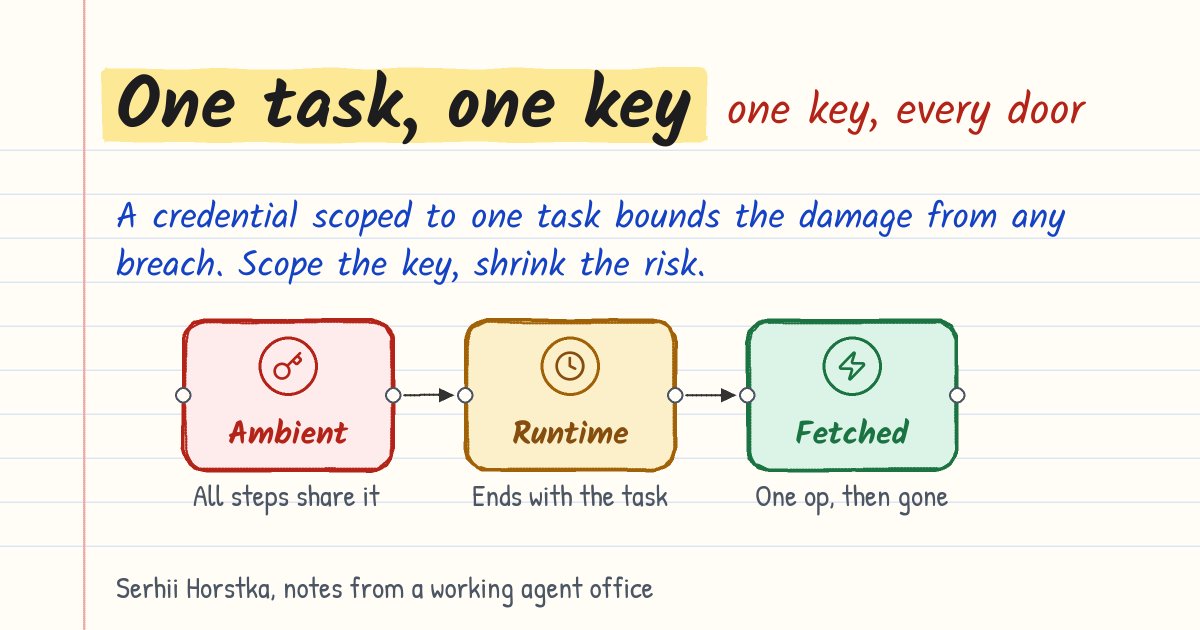
When an AI agent holds more access than its task needs, a breach costs more than it has to. Here is how scoping credentials to each task limits the damage.
8 min read